 ADevGuide
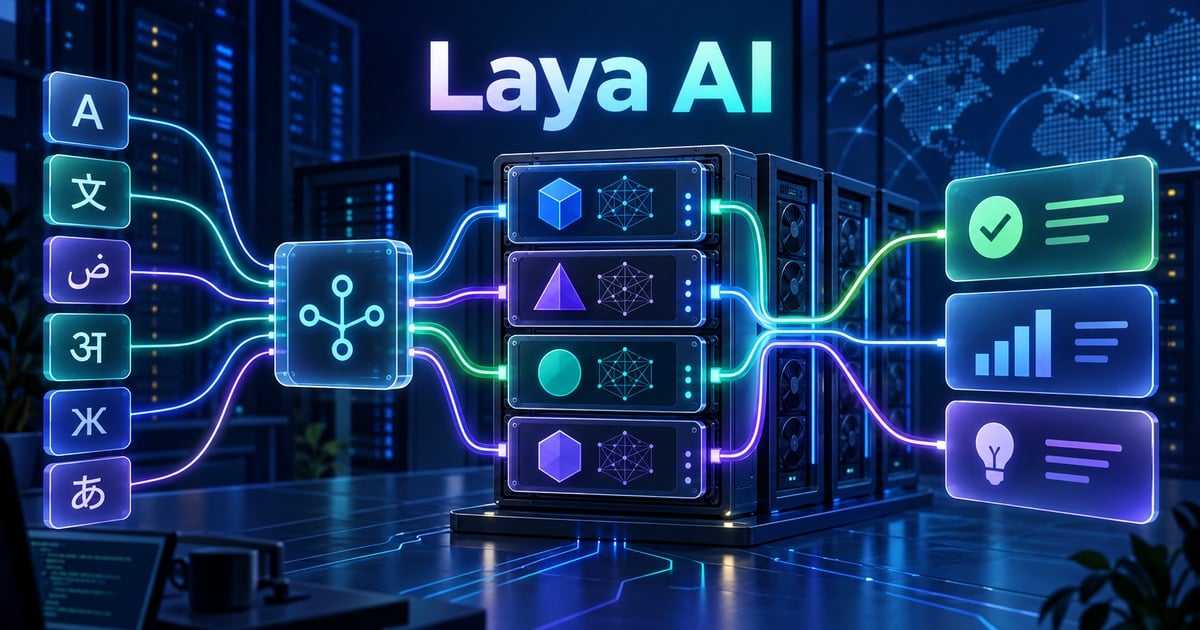
Many AI systems use a large generative model for decisions that are much smaller than conversation: route a ticket, detect a phishing message, score urgency, or decide whether a prompt needs review. That can be expensive and slow, especially when the application only needs a known label, score, or probability.
Laya is an open-source decision model family from Convai Innovations that targets this gap. It evaluates a state with typed questions and returns structured decisions rather than generating a response for a person to read. This guide explains what Laya AI is, how its checkpoints and router work, how to run it locally, and which limitations matter before production use. For related architecture context, browse the AI Engineering hub, the LLM agents hub, and our guides to OpenClaw and agentic AI.
Last Updated: September 22, 2026
Table of Contents
Open Table of Contents
- What Is Laya AI?
- Why Laya Uses a System 1 Design
- How Laya Works
- The Three Laya Decision Primitives
- Running Laya Locally
- Best Use Cases for Laya
- Laya Performance and Benchmark Claims
- Laya Limitations and Trade-Offs
- Laya in a Production AI Architecture
- Frequently Asked Questions (FAQs)
- Conclusion
- References
- YouTube Videos
What Is Laya AI?
Laya is a family of non-autoregressive, open-weight AI decision models from Convai Innovations. Instead of generating text one token at a time, Laya evaluates typed questions against a state and returns a bounded answer such as a category, score, or yes-or-no probability.
The core interface looks like this:
State + typed questions -> Laya checkpoint -> typed answers + probabilitiesThe model is intended for application decisions, not for chat. A customer support platform might pass an incoming message and ask which queue should receive it, how urgent it is, and whether the customer asks for a refund. The application can then route the ticket, request more context, or call a generative LLM for a polished reply.
This design is useful because the application owns the answer space. If a Choice question has four valid queues, the downstream system does not need to guess whether a language model invented a fifth label. The model can still make an incorrect judgment, but the interface is explicit and easier to test.
Why Laya Uses a System 1 Design
Convai Innovations frames Laya as a System 1 decision model: a fast, focused component for simple judgments inside a larger system. The name is related to the familiar System 1 and System 2 distinction, but developers should read it as an architecture choice rather than as a claim that the model reproduces human psychology.
The practical problem is common. A generative LLM is asked to produce JSON for every classification step, then the application parses and validates the result. Even with structured-output APIs, the workflow can still be slower and more expensive than a small model that was built around a bounded decision interface.
Laya trades generality for a narrower contract:
- It is good at high-volume decisions with a known answer shape.
- It can run locally instead of requiring a hosted API call.
- It includes a multilingual checkpoint and a router for language selection.
- It requires more ownership from the developer than a managed decision API.
That last point matters. Self-hosting removes a per-request API bill, but it adds packaging, hardware, model loading, observability, calibration, upgrades, and security work. The right comparison is total workflow cost, not only the inference price.
How Laya Works
Laya evaluates a state with one or more typed questions. A router can select a checkpoint before the forward pass, then the application applies its own thresholds and actions.
flowchart TD
    A[Text or JSON state] --> B[Laya Router]
    B --> C{Language or task}
    C -->|English| D[English checkpoint]
    C -->|100+ languages| E[Multilingual checkpoint]
    C -->|Typed workflow| F[Typed-decisions checkpoint]
    D --> G[Choice, Score, or Noul]
    E --> G
    F --> G
    G --> H{Application policy}
    H -->|Confident| I[Route, filter, or act]
    H -->|Uncertain| J[Human or generative model]
Typed Decisions
The model does not need to write a prose explanation to answer a bounded question. Instead, the question defines the possible output space. That is useful for software because the application can branch on the result directly.
For example, a ticket state might produce:
{
  "queue": "infrastructure",
  "urgency": 2.87,
  "churn_risk": 0.914
}
These values are not business actions. The application still decides whether an urgency score should page someone, whether a churn score should create a task, and whether a human must approve the next step.
The Laya Checkpoints
The official Laya site describes three checkpoints bundled under one Hugging Face model hub:
| Checkpoint | Backbone | Parameters | Primary strength |
|---|---|---|---|
convaiinnovations/laya | ModernBERT-large | 421M | English classification, guardrails, and email triage |
convaiinnovations/laya-multilingual | mmBERT-base | 322M | 100+ languages and cross-lingual decisions |
convaiinnovations/laya-typed-decisions | ModernBERT-large | 421M | Agent observability, support, invoices, and security alerts |
The choice of checkpoint is part of the engineering task. A model trained for English text classification should not silently receive scripts it tokenizes poorly. Conversely, a multilingual model may be the right default for a global product even if its English score differs from the English-specialized checkpoint.
The Router
Laya’s Router can inspect the input and select a checkpoint. The official implementation describes script detection across multiple writing systems and a preload mode that keeps the required models in memory to avoid cold swaps.
Routing is not merely a convenience feature. The wrong checkpoint can produce high confidence on a language it does not understand. That means the router is part of the correctness boundary, and it needs its own tests for language detection, mixed-script inputs, empty text, and unusual JSON structures.
The Three Laya Decision Primitives
Laya uses the same useful primitive shapes as other System 1 decision designs.
| Primitive | Question shape | Returned value | Example |
|---|---|---|---|
| Choice | Select one option | Choice plus distribution and confidence | billing, technical, or support |
| Score | Place the input on ordered levels | Expected level plus distribution | Low, medium, or critical |
| Noul | Estimate whether a statement is true | Probability from 0 to 1 | Is this message phishing? |
Choice is best for unordered categories. Score is best when the levels have an order and a written definition. Noul is best when the probability of a yes-or-no statement is useful to the surrounding policy.
Do not use the primitive name as a substitute for a clear question. “Is this good?” has no stable meaning until the developer defines what good means, for which user, and against which evidence.
Running Laya Locally
Laya is designed for local inference through its Python package. The following example follows the current quickstart pattern published by Convai Innovations.
pip install laya>=0.3.3from laya import Router
router = Router(preload=True)
ticket = {
"subject": "Production API outage and billing dispute",
"body": "Our API has failed since 6 AM. We lost transactions and need an SLA refund.",
}
questions = {
"queue": {
"type": "choice",
"instructions": "Which engineering queue owns this ticket?",
"criteria": {
"infrastructure": "Outages, networking, or database failures.",
"billing": "Refunds, invoices, or SLA credits.",
"security": "Breaches or vulnerability reports.",
"support": "General customer questions.",
},
},
"urgency": {
"type": "score",
"instructions": "How urgent is this ticket?",
"criteria": ["Low", "Medium", "High", "Critical blocker"],
},
"churn_risk": {
"type": "noul",
"instructions": "Does the customer express a serious risk of cancellation?",
},
}
result = router.predict(ticket, questions)
# The application owns the side effect. The model only supplies evidence.
queue = result["answers"]["queue"]["choice"]
urgency = result["answers"]["urgency"]["score"]
churn_risk = result["answers"]["churn_risk"]["noul"]
if queue == "infrastructure" and urgency >= 2.5:
print("Page the infrastructure on-call")
elif churn_risk >= 0.9:
print("Create a customer-success review")
else:
print("Use the normal support workflow")The code is intentionally split into model output and application action. If the model is wrong, the policy layer is where you add thresholds, fallbacks, idempotency, approvals, and logging. That separation is more maintainable than embedding all side effects in an opaque prompt.
Best Use Cases for Laya
Local ticket routing
Teams that cannot send support content to a hosted service can run a model inside their own network. The privacy benefit depends on the whole deployment, including logs, model downloads, observability, and administrator access.
Multilingual classification
The multilingual checkpoint and router target applications that receive content in many scripts or languages. Always test the languages and domains that matter to your business instead of treating a model’s language count as a quality guarantee.
Email spam and phishing detection
A bounded decision model can classify messages before they reach a more expensive workflow. For security use cases, combine the output with deterministic checks, threat intelligence, and a review path for high-impact actions.
Guardrails and prompt screening
Laya can act as a first-pass classifier for prompt injection, jailbreak-like requests, or content policy categories. It should not be the only security boundary. Keep authorization, isolation, and tool permissions outside the model.
Retrieval filtering
A retrieval pipeline can score whether a passage is relevant before sending it to a generative model. This can reduce context size, but it can also remove the one passage needed to answer a rare question. Measure recall as well as precision.
Laya Performance and Benchmark Claims
Convai Innovations reports a 32.8 millisecond median latency for a single question on a single GPU and 7.2 milliseconds per question when ten questions are batched. The site also reports a 100-plus-language routing story, open Apache 2.0 weights, and comparisons with TypeSafe Jev.
Those are published claims from the project team, not a universal guarantee. Latency changes with hardware, batch size, model loading, sequence length, quantization, Python overhead, and the network around the service. Accuracy changes with the domain, label design, fine-tuning data, and calibration procedure.
Evaluate Laya on your own workload with at least these measurements:
| Metric | Why it matters |
|---|---|
| Accuracy and macro F1 | Shows whether the labels are useful across classes |
| Calibration error | Shows whether probabilities reflect observed outcomes |
| Recall on rare classes | Prevents fast models from silently dropping important cases |
| P50 and P99 latency | Captures both normal and tail behavior |
| Cold-start time | Matters when models are loaded on demand |
| Memory and GPU utilization | Determines deployment cost and capacity |
Laya Limitations and Trade-Offs
It is not an open-ended chatbot
Laya does not replace a generative model for writing, long explanations, translation, or complex tool planning. Its value comes from making a narrow decision cheap and explicit.
Choice cardinality matters
The official project reports a sharp drop for large Choice spaces, including a Banking77 stress test with 77 labels. If your taxonomy is large, use a hierarchical design: first choose a broad family, then ask a second question with a smaller set of labels.
Base weights may need fine-tuning
The project reports that out-of-the-box base models can perform close to random on some typed-decision tasks, while stronger benchmark numbers use fine-tuning. Treat Laya as a model you may need to specialize, not as a zero-shot oracle for every domain.
Calibration is a deployment task
Raw scores are not automatically safe thresholds. Fit or validate calibration on representative data, then re-check it after changing the domain, language mix, checkpoint, or preprocessing.
Self-hosting creates operational work
You own model artifacts, hardware, autoscaling, health checks, rollout strategy, dependency updates, and security. An open license reduces vendor dependency, but it does not eliminate engineering responsibility.
Laya in a Production AI Architecture
A practical Laya pipeline can sit before a larger LLM:
- Normalize the input without deleting evidence the classifier needs.
- Route to a checkpoint based on language or task.
- Ask multiple atomic questions in one forward pass where possible.
- Apply thresholds and deterministic rules in application code.
- Escalate uncertainty to a human or a generative model.
- Log outcomes so calibration and class drift are visible.
For example, an agent that handles customer requests might use Laya for language detection, queue selection, urgency, and policy flags. It can then select a retrieval collection and a prompt for a generative model. The generative model writes the response, while the application remains responsible for permission checks and the final send action.
This resembles the broader tool-oriented architecture described in MCP explained for developers: separate the model’s judgment from the tools and policies that produce side effects. It also complements the modular capabilities described in AI agent skills.
Frequently Asked Questions (FAQs)
Is Laya an LLM?
Laya is a decision model family rather than a conventional text-generating chatbot. It evaluates a state against typed questions and returns bounded decisions, scores, and probabilities.
Is Laya open source?
Convai Innovations publishes Laya weights and code under an Apache 2.0 model on its official project and model hub. Check the exact repository and checkpoint license before redistributing a derivative or embedding it in a commercial product.
Can Laya run without an API call?
Yes. The project is designed for local inference through its Python package and Hugging Face checkpoints. Local operation still requires suitable compute, model downloads, memory, and an operational plan.
Is Laya faster than Jev?
Convai Innovations reports faster benchmark latency for its routed Laya setup than the Jev numbers it compares against. That is a project-reported comparison under stated conditions, not a guarantee for every hardware, language, batch size, or workload. Run a matched benchmark before choosing.
What should I do when Laya is uncertain?
Do not force every result into an automatic action. Use probability or confidence thresholds, add an other label where appropriate, send uncertain cases to a human or generative model, and record the final outcome for later evaluation.
Can Laya replace a large generative model?
Not for general conversation or writing. Laya can reduce how often a large model is called for classification, routing, scoring, and guardrails. In most products it is a specialized layer in a hybrid architecture.
Conclusion
Laya AI is an open-source System 1 decision model family for fast, typed judgments inside software. Its main attractions are local deployment, Apache 2.0 weights, multilingual routing, and a small interface built around Choice, Score, and Noul decisions.
The trade-off is that you inherit more responsibility. Large label sets need hierarchical classification, base models may need fine-tuning, probability calibration must be tested, and self-hosting requires real operations work. Laya is most promising when the task is high-volume, bounded, privacy-sensitive, and easy to evaluate.
References
- Laya official project site
- Laya on Hugging Face
- Laya GitHub repository
- TypeSafe AI: Introducing System One Models and Jev
YouTube Videos
- “JEV: How It Works and What You Can Build” - Riley Brown [https://www.youtube.com/watch?v=o1CogAtWdBk]
This video focuses on Jev, but it is useful background for the shared System 1 decision-model pattern that Laya also targets. The official Laya project links above remain the primary sources for Laya-specific behavior and benchmarks.