 ADevGuide
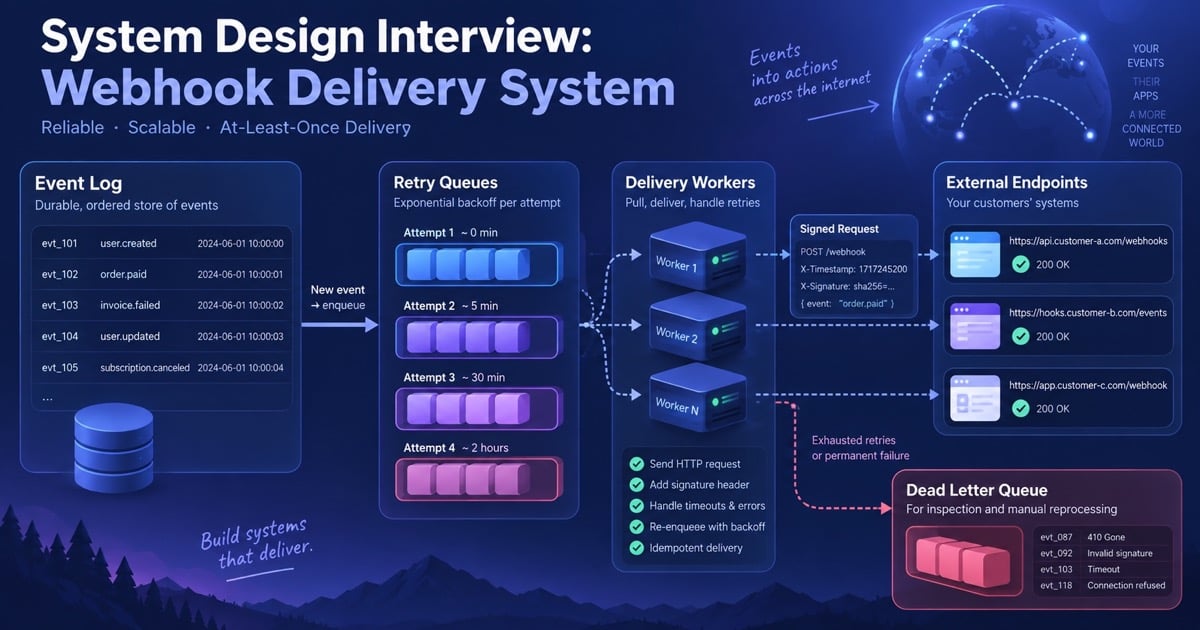
Webhook Delivery System is a classic system design interview prompt because it forces you to make a clear choice about reliable delivery to untrusted endpoints. Use the system design interview cheatsheet for the reusable framework, then compare this design with the System Design hub and Backend Interview Mastery.
Table of Contents
Open Table of Contents
- Interview Framework: How to Approach This Problem
- Step 1: Clarifying Requirements
- Step 2: Core Assumptions and Constraints
- Step 3: High-Level Architecture
- Step 4: The Hardest Problem - reliable delivery to untrusted endpoints
- Step 5: durable event log plus per-destination retry queues
- Step 6: Database Design and Storage
- Step 7: Scaling the System
- Step 8: Security and Permissions
- Step 9: Handling Edge Cases
- Step 10: Performance Optimizations
- Real-World Implementations
- Common Interview Follow-Up Questions
- Conclusion
- References
- YouTube Videos
Interview Framework: How to Approach This Problem
Allocate five minutes to clarify the user promise, two minutes to state assumptions, ten minutes to draw the architecture, twenty minutes to deep-dive into reliable delivery to untrusted endpoints, and the final ten minutes to scale, secure, and test it. Think aloud, name uncertainty, and ask the interviewer whether the trade-off matches the product requirement.
Step 1: Clarifying Requirements
Ask: What is the core user action? Is completion synchronous or eventual? What correctness guarantee matters most? What is the peak rate and payload size? Which regions and tenants are in scope? What is the acceptable P99 and availability target? What must be auditable?
For this design, support the primary webhook delivery system flow, retries, status inspection, and operator recovery. Keep optional ranking, multi-region writes, and advanced analytics out of the MVP unless the interviewer asks for them.
Step 2: Core Assumptions and Constraints
Assume 100,000 events/sec; 1 million destinations; delivery within minutes. Choose an availability target of 99.9% for the control plane and a webhook delivery system-appropriate user SLO. Requests carry an authenticated tenant or user identity, and every mutating request has an idempotency key. Eventual consistency is acceptable for status views, but the authoritative invariant is checked transactionally.
Step 3: High-Level Architecture
The main components are Producer API, Event Log, Scheduler, Delivery Workers, Destination Registry, DLQ, Metrics. Keep the API stateless, isolate asynchronous work behind durable queues, and make the system of record explicit.
System Flow Diagram
flowchart TD
    A[Producer Service] --> B[Event Log]
    B --> C[Per-Destination Scheduler]
    C --> D[Delivery Worker Pool]
    D --> E[Customer Endpoint]
    E --> F[Signed Response]
    F --> G[Attempt and Delivery Store]
    C -. exhausted .-> H[DLQ and Replay]
    G --> I[Delivery Status API]
Architecture Walkthrough
- The producer appends one immutable event with an event ID and schema version to the log.
- A destination scheduler creates a delivery task and applies per-tenant, per-host concurrency limits.
- Workers sign the payload, enforce a connect/read deadline, and classify the response as success, transient, or permanent.
- Transient failures use destination-specific backoff; exhausted attempts enter a DLQ with the complete attempt history.
- Consumers deduplicate by event ID, so a lost 2xx response can be retried without applying the business action twice.
- The status API exposes attempt age, next retry, endpoint health, and a permissioned replay operation.
The destination is untrusted and can be slow forever. Per-destination scheduling and durable attempts prevent one customer endpoint from consuming the entire delivery fleet.
Step 4: The Hardest Problem - reliable delivery to untrusted endpoints
The difficult case is a slow or duplicated operation that overlaps a failure. Three approaches are plausible:
Approach 1: Synchronous request chain
The API calls every dependency before responding. It is easy to explain and provides immediate feedback, but one slow dependency consumes request capacity and a lost response makes the outcome ambiguous. It fails under bursty load.
Approach 2: Best-effort asynchronous events
The API emits an event and returns immediately. This absorbs spikes, but without a durable state machine, duplicate delivery and lost events leave the user unable to know whether work completed. It is not enough for the authoritative invariant.
Approach 3: Durable state machine with leased workers
Persist the intent, publish through an outbox, claim work with a lease, and make each transition idempotent. A worker can resume after a crash, while the status API exposes PENDING, SUCCEEDED, and FAILED states. This is the chosen approach because it makes failure visible and replayable.
Step 5: durable event log plus per-destination retry queues
Choose durable event log plus per-destination retry queues. The decision trades a small amount of workflow complexity and eventual completion for bounded API latency, independent scaling, and a recoverable audit trail. Use a monotonically increasing version on each state transition so stale workers cannot overwrite a newer result.
A minimal worker contract is:
async function process(command: Command) {
  const claimed = await store.claim(
    command.id,
    command.leaseId,
    command.version
  );
  if (!claimed) return; // another worker won, or the command is already complete
  try {
    const result = await performIdempotently(command);
    await store.complete(command.id, result, command.version + 1);
  } catch (error) {
    await store.failOrRetry(command.id, classify(error), command.version + 1);
  }
}
Step 6: Database Design and Storage
Classify data by access temperature. Hot state and leases need a low-latency transactional store; recent results and indexes are warm; raw payloads, audit history, and old artifacts belong in object or columnar storage.
Use these core records: events, subscriptions, attempts, destinations. Include an immutable ID, tenant or owner, current status, version, idempotency key, created and updated timestamps, correlation ID, and error code. Index the idempotency key uniquely, status plus next-attempt time for workers, and owner plus created time for queries. Never use a cache as the sole source of the correctness invariant.
Step 7: Scaling the System
Start with 100,000 events/sec; 1 million destinations; delivery within minutes. Identify four bottlenecks:
- Ingress: use stateless replicas, connection limits, and rate limits.
- State store: partition by tenant or entity ID, batch noncritical writes, and keep transactions short.
- Queue/workers: partition by ordering key, autoscale on queue age, and apply backpressure when downstream capacity is full.
- Read path: maintain a projection, cache safe immutable results, and paginate history.
If one worker handles 100 operations/second and peak demand is 10,000 operations/second, 100 workers meet the raw rate; provision 2x for failures and burst headroom. If each operation fans out to three calls, budget 30,000 downstream calls/second before retries. State the math and then ask which number the interviewer wants to optimize.
Step 8: Security and Permissions
Authenticate users or service principals at the edge and authorize every state transition against tenant ownership. Scope idempotency keys to the tenant, encrypt sensitive payloads at rest, and redact secrets from logs. Sign internal events, rotate keys, and use short-lived worker credentials.
For operator replay, require a separate role, a reason, an approval or ticket, and an immutable audit record. Rate-limit status and mutation endpoints, validate uploaded or embedded content, and prevent a tenant from selecting another tenant’s IDs.
Step 9: Handling Edge Cases
- Client timeout: return the stored status for the same idempotency key; never blindly repeat the side effect.
- Worker crash: lease expiry makes the command claimable; version checks prevent stale completion.
- Duplicate event: the inbox or unique command key turns it into a no-op with the original result.
- Downstream timeout: honor the remaining deadline, retry only idempotent transient failures, and move exhausted work to a DLQ.
- Region outage: fail over reads and accept writes only where the consistency contract remains true; reconcile after recovery.
Step 10: Performance Optimizations
Use outbox, exponential backoff, HMAC signatures where it matches the workload. Batch queue acknowledgements, compress large payloads, cache immutable metadata, and keep hot worker state in memory with durable checkpoints. Use adaptive concurrency so workers do not overwhelm a dependency.
Measure end-to-end latency, queue age, success rate, retry amplification, state-store CPU, and stale projection age. A faster average that increases duplicate work or tail latency is not an optimization.
Real-World Implementations
Stripe and GitHub demonstrate the same principles at production scale: durable event logs, per-destination retries, HMAC signatures, and explicit replay. A practical stack can combine an outbox, exponential backoff, endpoint health state, and OpenTelemetry delivery traces. The exact vendor is less important than the idempotent-consumer contract, failure boundary, and operational evidence.
Common Interview Follow-Up Questions
1. How do you guarantee idempotency?
Persist a scoped idempotency key with a unique constraint and store the first result. Every retry returns that result or a clearly pending state. Downstream calls receive the same key so provider retries are safe too.
2. What happens when the queue is unavailable?
Commit the authoritative intent only if the outbox can record the event in the same transaction. A relay can publish later. If the state store is unavailable, reject new work rather than acknowledging an intent that cannot be recovered.
3. How do you handle ordering?
Partition commands by the entity whose order matters and attach a version to every transition. Workers reject a version older than the stored one. If global ordering is requested, explain its throughput and availability cost.
4. How do you scale across regions?
Prefer local reads and regionally partitioned writes when the business allows it. Use a clear home region or consensus authority for single-writer invariants, and replicate projections asynchronously. During a partition, state which operations fail and how reconciliation works.
5. How do you operate the system?
Define SLOs for API latency, completion time, freshness, and recovery. Alert on oldest queue age, stuck leases, retry amplification, and invariant violations. Provide dashboards, runbooks, bounded replay, and a kill switch for expensive work.
Conclusion
A strong webhook delivery system interview answer is a sequence of explicit choices: requirements, one authoritative invariant, a durable state machine, idempotent commands, bounded asynchronous work, and measurable recovery. Draw the happy path, then spend most of the interview on the failure that makes the design non-obvious.
References
YouTube Videos
- “System Design Interview: Webhook Delivery System” - Hello Interview [https://www.youtube.com/watch?v=DOFflggE_0Q]