 ADevGuide
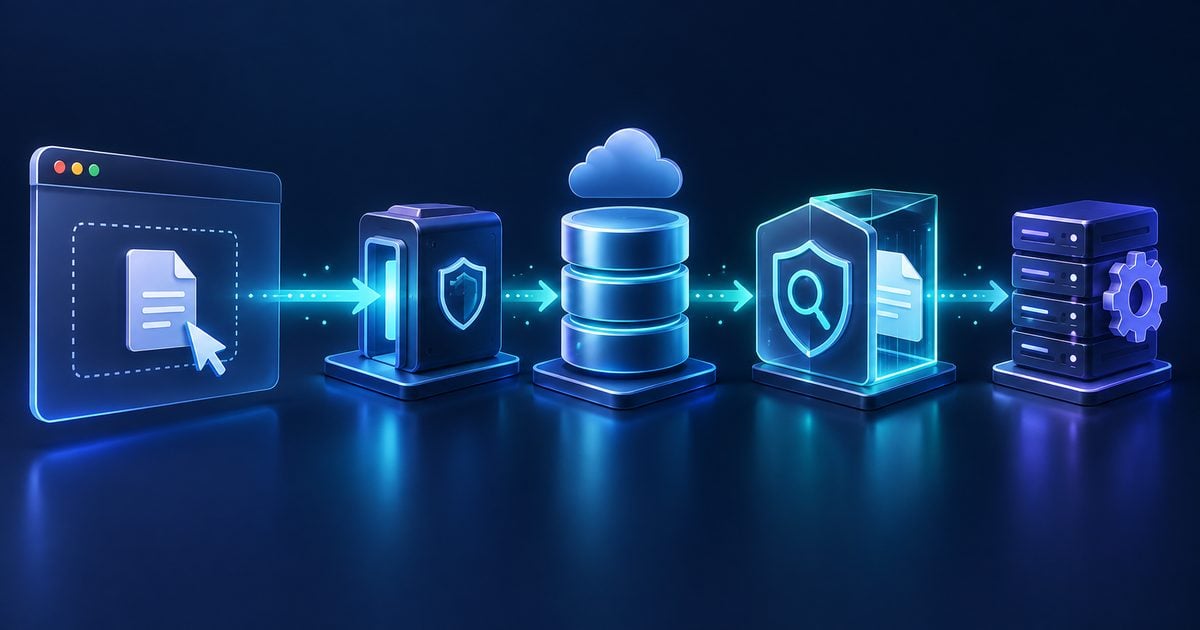
When someone uploads a profile photo, the browser does not put the image inside JSON and hope for the best. It reads bytes from the selected file, sends a multipart request or uploads directly to object storage, and the backend validates, stores, and often processes the file after the response.
This guide explains how file upload works in web applications from browser selection to secure storage. It builds on How APIs Work: A Simple Guide for Beginners and How Background Jobs Work in Web Applications. Continue through the Practical Backend Engineering series or browse Backend Development for related guides.
Table of Contents
Open Table of Contents
The Upload Lifecycle
The browser exposes a selected file through the File API. Your client then sends its bytes, metadata, and form fields to an upload endpoint. The server verifies the request, writes the original to durable storage, records metadata, and returns a file identifier or URL.
flowchart TD
    A[User selects file] --> B[Browser validates basic limits]
    B --> C[Upload API or signed storage URL]
    C --> D[Server validates identity and file]
    D --> E[Object storage]
    E --> F[File metadata database record]
    F --> G[Return upload result]
    E --> H[Background scan and transforms]
The important design choice is to separate the original file from its metadata. Store the bytes in object storage and keep a database record for ownership, content type, size, status, and storage key. A database blob can be reasonable for small, tightly transactional documents, but object storage is usually better for large files and delivery through a CDN.
Multipart Form Data Explained
multipart/form-data is an HTTP format that sends several named parts in one request. One part can be text such as displayName; another can contain the file bytes and file name. The browser creates the boundary markers automatically when you use FormData.
async function uploadAvatar(file) {
  const form = new FormData();
  form.append("avatar", file, file.name);

  const response = await fetch("/api/uploads/avatar", {
    method: "POST",
    body: form,
    // Do not set Content-Type manually. The browser adds the multipart boundary.
  });

  if (!response.ok) throw new Error("Upload failed");
  return response.json();
}
The browser-supplied Content-Type is not proof of the real file type. It is a claim from an untrusted client. The server should inspect the file signature, enforce a small allowlist, and assign its own storage name.
Server Upload vs Direct-to-Storage Upload
With a server upload, the browser sends bytes to your application, which then writes them to storage. This is simple for small files and lets your service inspect every upload before storage. The trade-off is that application servers handle the full bandwidth and must be sized for spikes.
With a direct-to-storage upload, your backend authenticates the user and issues a short-lived, limited signed URL. The browser uploads directly to storage, then calls your API to finalize the metadata. This removes large byte streams from the application tier, but the signed URL must restrict object key, size, content type, expiry, and operation.
A Secure Upload Endpoint
async function createUpload(req, res) {
  const file = req.file;
  if (!file) return res.status(400).json({ error: "A file is required" });

  if (file.size > 5 * 1024 * 1024) {
    return res.status(413).json({ error: "File is too large" });
  }

  const detectedType = await detectFileType(file.buffer);
  if (
    !detectedType ||
    !["image/jpeg", "image/png"].includes(detectedType.mime)
  ) {
    return res.status(415).json({ error: "Unsupported file type" });
  }

  const storageKey = `uploads/${req.user.id}/${crypto.randomUUID()}.${detectedType.ext}`;
  await objectStore.put(storageKey, file.buffer, {
    contentType: detectedType.mime,
  });

  const record = await saveUpload({
    ownerId: req.user.id,
    storageKey,
    status: "pending",
  });
  await jobs.add("scan-upload", { uploadId: record.id });
  return res.status(201).json({ id: record.id, status: record.status });
}
The endpoint generates the storage key instead of trusting a filename. It also returns before expensive scanning or thumbnail creation finishes. The original should not become public until required safety checks pass.
Validation and Storage Rules
Apply several controls together:
- authenticate and authorize the uploader;
- allow only required file types and inspect file signatures;
- enforce size, count, and rate limits before buffering too much data;
- generate random storage names outside the web root;
- store files with private access by default;
- scan untrusted uploads and serve transformed previews when possible.
Do not rely only on extensions such as .jpg. A renamed executable can have a harmless-looking extension. OWASP recommends an allowlist, size limits, generated names, and storage outside the web root because each control covers a different failure mode.
Processing Files After Upload
Virus scanning, thumbnail generation, OCR, media transcoding, and metadata extraction can take seconds or minutes. Put them in a durable background queue, update the file status, and expose a clear pending state to the user. A retry must be idempotent: processing the same upload twice should not produce conflicting records or overwrite an approved file with an unverified variant.
Common Mistakes
Trusting the original filename
Names can collide, contain path-like characters, or misrepresent the type. Generate an opaque key and keep the original name only as display metadata if you need it.
Making uploads public immediately
Public storage can expose malware, private documents, or predictable URLs. Keep uploads private until authorization and processing rules are satisfied.
Loading huge files into memory
Large buffers can exhaust a server under concurrent traffic. Stream uploads when your framework and storage provider support it, and reject excessive content length early.
Interview Questions
1. Why is multipart form data used for uploads?
It carries file bytes and normal fields in one HTTP request. It avoids encoding binary data as JSON and lets the browser include per-file metadata such as the submitted name and declared type.
2. Why should a backend inspect file content?
Extensions and client MIME types are untrusted input. Inspecting file signatures helps prevent a malicious file from being accepted just because it was named like an image.
3. When would you use a signed upload URL?
Use it for large or frequent uploads when object storage should receive bytes directly. The backend still controls authorization and must make the URL short-lived and narrowly scoped.
4. What work belongs in the request path?
Authentication, authorization, basic validation, durable original storage, and metadata creation usually belong in the request. Scanning and transformations can happen asynchronously when the product supports a pending state.
5. How do you prevent one user from accessing another user’s file?
Store ownership with the metadata record, authorize every read against that record, keep storage private, and issue short-lived download URLs only after the permission check.
Conclusion
A robust upload flow treats files as untrusted bytes. Use multipart form data or constrained signed URLs, validate before accepting, keep originals private, separate metadata from storage, and send expensive processing to monitored workers.
References
YouTube Videos
- “File Uploads in Node.js” - Web Dev Simplified
https://www.youtube.com/watch?v=Hf4ps7q2WCY - “How File Uploads Work” - Hussein Nasser
https://www.youtube.com/watch?v=co4iQUgT2ZY