 ADevGuide
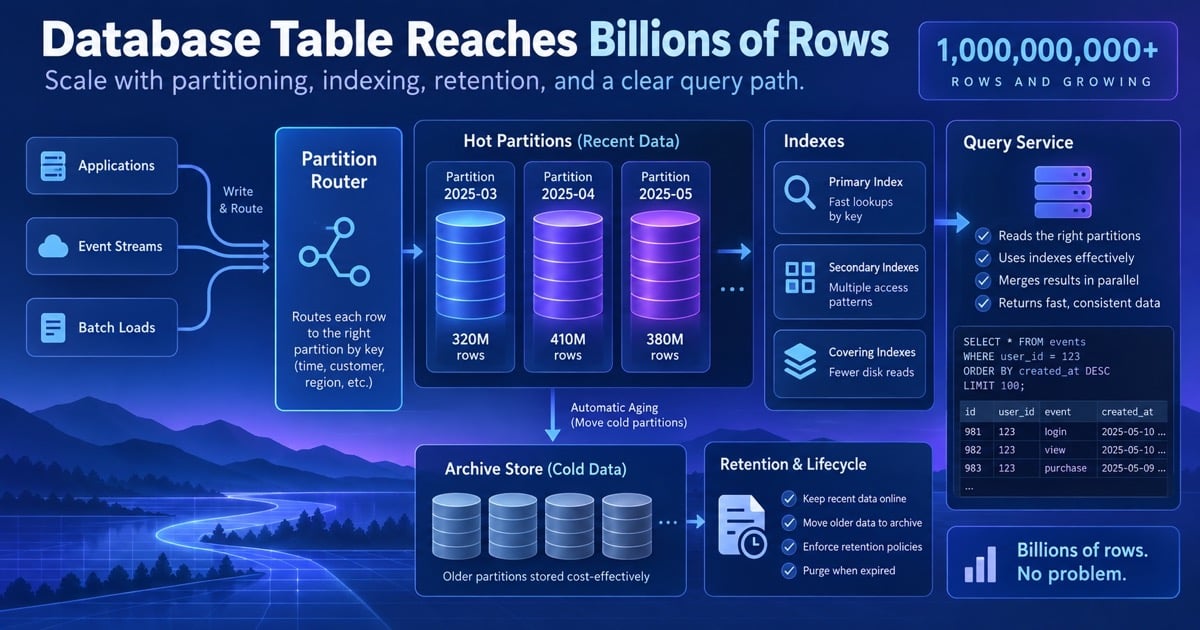
This scenario asks you to scale a table to billions of rows using partitioning, archival, indexes, retention, and online maintenance. Treat it as an incident and design prompt: state the invariant, expose the failure boundary, and choose a mitigation that can be rolled back. Continue from the Backend Interview Mastery series and the system design interview cheatsheet.
Table of Contents
Open Table of Contents
- 1. Interview Question
- 2. Clarifying Questions
- 3. Naive Design
- 4. Why It Fails
- 5. Better Design
- 6. Architecture
- 7. Data and Race Analysis
- 8. Failure Handling
- 9. Scaling and Capacity
- 10. Trade-offs
- 11. Observability
- 12. Interview Follow-Ups
- 13. Related Practice
- References
- YouTube Videos
1. Interview Question
“An on-call engineer reports that we must scale a table to billions of rows using partitioning, archival, indexes, retention, and online maintenance. How would you make the system correct under concurrency, retries, and partial failure?”
2. Clarifying Questions
Ask what the user-visible invariant is, what is authoritative, the peak rate, acceptable latency, retry policy, ordering requirement, failure scope, and recovery objective. Assume Write path, partition router, hot partitions, archive store, query service.
3. Naive Design
Start with one synchronous service and a direct call to the dependency. It is easy to deploy, but it couples request latency to every downstream operation and leaves no durable record for work that timed out. A process-local cache or lock also fails when requests land on another replica.
4. Why It Fails
The naive path violates correctness when two requests observe the same state, a response is lost after a commit, or a worker dies mid-operation. It also scales the wrong resource: retries and unbounded concurrency amplify load exactly when the dependency is unhealthy.
5. Better Design
Persist an intent or event before performing the side effect, attach an idempotency key, and make state transitions monotonic. Use a bounded queue for asynchronous work, a lease for worker ownership, and a dead-letter path for exhausted attempts. Return a pending status when the outcome is uncertain instead of guessing.
6. Architecture
The core components are 10 billion rows; 10,000 writes/sec; bounded queries. Keep the request path thin and route work through durable state and a queue.
flowchart TD
    A[Query API] --> B[Partition Router]
    B --> C[Hot Partitions]
    B --> D[Cold Archive]
    C --> E[Indexes and Query Plans]
    F[Online Backfill] --> C
    F --> G[Progress Checkpoint]
G -. pause .-> F- Route queries by a partition key and reject unbounded scans at the API.
- Backfill in resumable chunks with checkpoints, rate limits, and lock-age limits.
- Validate row counts and checksums before advancing the migration marker.
- Move cold ranges to an archive tier while keeping hot partitions indexed.
- Pause backfill automatically when write latency or replication lag breaches the budget.
7. Data and Race Analysis
Use a state table with id, owner or tenant, idempotency key, status, version, lease expiry, attempt count, and timestamps. Add a unique index for the key and a compare-and-set on version. If two workers race, only the worker holding the current lease and version may commit. Keep the system of record authoritative; caches and projections may be stale.
8. Failure Handling
A timeout becomes UNKNOWN or PENDING until the system can query or reconcile the dependency. Retry only transient, idempotent operations with exponential backoff and jitter. Expired leases make work claimable, while a DLQ preserves payload, error, correlation ID, and attempt history. Recovery starts with the oldest pending item, not the newest alert.
9. Scaling and Capacity
Assume a table growing to 5 billion rows with continuous writes; size partition maintenance, backfill throughput, indexes, and archive lag. A 1,000-row/second backfill would take months, so parallelize only within the write and lock budget.
10. Trade-offs
Synchronous completion gives immediate feedback but couples availability and latency. Asynchronous completion absorbs bursts and enables replay but requires a status API and eventual-consistency language. Strong serialization protects the invariant but can reduce throughput; partitioning improves scale while narrowing the ordering guarantee.
11. Observability
Track request rate, error rate, P50/P95/P99, queue age, oldest pending work, lease expiry, retry amplification, state-store saturation, and invariant violations. Correlate logs, traces, and events with one ID. Alert on trend and age, not only instantaneous error percentage.
12. Interview Follow-Ups
Scenario-Specific Follow-Ups
1. How do you choose a partition key?
Start with the dominant query predicates and write distribution, then test for hot partitions and cross-partition joins. A time key helps retention but can create a newest-partition hotspot.
2. How do you backfill safely?
Use resumable chunks with checkpoints, rate limits, and a lag-aware pause condition. Validate counts and checksums per chunk before advancing the cutover marker.
3. What changes at query time?
Require bounded predicates, reject accidental full scans, and maintain indexes only for proven access paths. Move cold ranges to an archive tier when the product does not need hot latency.
1. How do you make retries safe?
Store a scoped idempotency key and the first result under a unique constraint. Pass that key to downstream providers and return the stored result on duplicate requests. A retry after an uncertain timeout therefore converges on one business outcome.
2. What if the queue is unavailable?
Commit the intent only when an outbox row is written in the same transaction. A relay can publish later. If the state store itself is unavailable, reject new work rather than acknowledging an unrecoverable request.
3. How do you handle a hot key?
Coalesce concurrent requests, shard or replicate the hot key when semantics allow, and rate-limit the caller. Do not simply increase concurrency against one serialized row. Measure per-key skew separately from fleet averages.
4. How do you recover after a region or dependency outage?
Pause nonessential work, cap retries, fail over only where the data contract permits, and reconcile after recovery. Replay a bounded range with the original IDs. Document which user operations return pending or retryable states.
5. What would you test before launch?
Run concurrent invariant tests, crash workers after each state transition, inject timeouts and duplicate events, and load-test the hottest partition. Verify dashboards, rollback, DLQ replay, and operator permissions. Test recovery time as a first-class SLO.
13. Related Practice
Read backpressure, timeouts, and observability.
References
YouTube Videos
- “Backend Distributed Systems Interview Scenario” - Hello Interview [https://www.youtube.com/watch?v=Ibf7wKf8MqU]